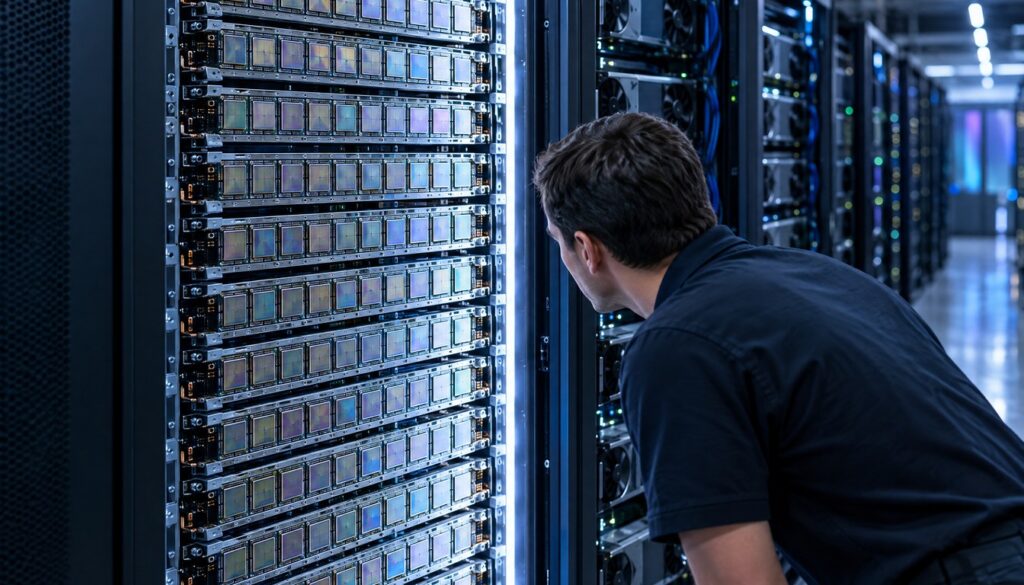
Microsoft used the OCP Global Summit stage on October 12, 2026, to unveil Maia 300, its third-generation custom AI accelerator, and to lay out a plan that pushes the company further away from buying every AI chip it needs from outside vendors. The announcement, detailed in a post on Microsoft’s own news site, frames Maia 300 as the chip that will eventually handle most of the AI inference work behind Microsoft’s own products and services.
That is a notable shift in tone. Microsoft has built custom silicon since 2023, but it has mostly talked about Maia chips as a supplement to Nvidia and AMD hardware inside Azure data centers. This time, the company said Maia 300 is meant to become the primary AI inference system for Microsoft products and services, with production deployments targeted for 2027. Microsoft also said it plans to scale Azure Maia to multi-gigawatt deployments starting that same year, a scope of ambition the company has not stated this explicitly before.
None of this means Microsoft is walking away from Nvidia or AMD. The company was careful to say its own silicon will mainly handle inference requests, which leaves plenty of room for GPUs to keep doing training and other workloads. But the direction is clear enough that outlets covering the story, including Axios, framed it as part of a broader pattern: the biggest cloud providers are no longer content to be customers alone. They want to be chipmakers too.
Microsoft’s Efficiency Claim: 40% More Tokens Per Megawatt
The headline number out of the Maia 300 announcement is efficiency, not raw speed. Microsoft said it expects Maia 300 to deliver 40% more tokens per megawatt than leading GPU-based systems. That framing matters because power, not chip supply alone, has become the binding constraint on how fast anyone can stand up new AI capacity. A data center can only pull so much electricity from the grid, so squeezing more useful output out of every megawatt translates directly into more AI services running per site.
Coverage of the figure, including reporting from CNBC, treated the 40% claim as the central selling point of the launch. It is worth being precise about what the number does and does not say. Microsoft has not published an independent, third-party benchmark confirming the figure, and the comparison is against unspecified “leading GPU-based systems” rather than a named competing chip. That is typical for a vendor’s own launch claim, and it should be read as Microsoft’s internal estimate until outside labs or customers publish their own numbers once Maia 300 systems start shipping.
Scott Guthrie, Microsoft’s Executive Vice President for Cloud and AI, put the efficiency pitch in blunt terms: “By improving efficiency across the system, we expect Maia 300 to deliver 40% more tokens per megawatt compared to leading GPU-based systems.” Guthrie also tied the chip to Microsoft’s broader deployment timeline, saying the company will scale its Azure Maia family to multi-gigawatt deployments starting in 2027, making Maia the primary inference system for Microsoft products and services.
Rack-Scale Leap: 96 Chips, Up to 7x the Throughput
Beyond the per-chip pitch, Microsoft is making a rack-level argument. The company said it expects 96 Maia 300 chips per data-center rack, twice the number of Maia 200 chips it packs into a rack today. Combined with per-chip gains, Microsoft said rack-scale Maia 300 systems are expected to deliver up to seven times the token throughput of Maia 200 systems.
That 7x figure is doing a lot of work in Microsoft’s pitch, since it compounds two separate improvements: more chips crammed into the same physical footprint, and better performance per chip. Doubling chip density while also improving per-chip efficiency is how you get a multiplier that looks dramatic on a slide but is difficult to verify without seeing the rack running real workloads. Microsoft has not disclosed a price for Maia 300, and nothing in the company’s public materials nails down exactly how the 7x figure was measured, so it is best treated as a target rather than a published benchmark result.
Rani Borkar, President of Azure Hardware Systems and Infrastructure at Microsoft, described the underlying philosophy this way: “It’s basically delivering more intelligence for every watt, every dollar, and every byte of memory by optimizing across the entire system.” That system-level framing, rather than a single chip spec, is how Microsoft wants the Maia 300 story to be read.
What’s Already Running: Inside the Maia 200
To understand why Maia 300 matters, it helps to look at what Microsoft’s current chip actually does. Maia 200 is built on TSMC’s 3nm process and packs 216GB of HBM3e memory with 7TB/s of memory bandwidth, along with 272MB of on-chip SRAM. Microsoft says the chip holds more than 140 billion transistors and includes native FP8 and FP4 tensor cores, the lower-precision math formats that make modern large language model inference cheaper to run.
On raw compute, Maia 200 is rated at more than 10 petaflops of FP4 performance and more than 5 petaflops of FP8 performance, all within a 750-watt system-on-chip thermal design power envelope. Microsoft has said Maia 200 is built to support models including OpenAI’s GPT-5.2, as well as Microsoft’s own Foundry platform and Microsoft 365 Copilot. In other words, Maia 200 is not a lab prototype. It is already wired into some of Microsoft’s highest-traffic AI products, which is exactly why the company feels comfortable describing Maia 300 as the next step rather than a first attempt.
That history matters for judging the Maia 300 claims. A company making its first attempt at custom silicon deserves more skepticism than one that has already shipped a chip carrying production traffic for a flagship product. Microsoft is in the latter category, even if Maia 300 itself is still a year-plus from real deployment.
Nvidia and AMD Still Hold the Floor
It is tempting to read a headline like “every major Nvidia customer is now a competitor” and conclude that Nvidia’s GPU business is suddenly under threat from its own buyers. That framing overstates what Microsoft actually confirmed. The available reporting backs increased custom-chip investment from major cloud providers, but it does not establish that every large Nvidia customer has become a direct rival chipmaker, and Microsoft itself said plainly that building its own silicon for inference does not mean it will stop buying Nvidia or AMD processors.
Nvidia remains the default supplier for AI training workloads at nearly every hyperscaler, and that is unlikely to change quickly. Even as Microsoft pushes Maia 300 toward inference duty, training the largest models still runs overwhelmingly on Nvidia’s GPU platforms, a dynamic shattered.io covered in detail when examining Nvidia’s buyback activity and broader financial position earlier this year. AMD, meanwhile, continues to compete for both training and inference business through its own accelerator lines, and nothing in Microsoft’s announcement changes that competitive picture for 2026 deployments already in the field.
What has changed is the long-run bargaining position. If Microsoft can genuinely move a large share of its own inference traffic onto Maia chips by 2027, that reduces how many GPUs it needs to buy for that specific purpose, even if total AI compute demand keeps climbing overall. That is a slow-moving shift, not an overnight one, and it depends entirely on Maia 300 performing in production the way Microsoft is currently describing it on a conference stage.
Maia 300 vs. Maia 200: What’s Confirmed and What’s Still Secret
The gap between what Microsoft has confirmed about Maia 200 and what it has confirmed about Maia 300 is wide. Maia 200 has a full public spec sheet. Maia 300, by contrast, has been described almost entirely in relative terms: percentage gains, multiples, and rack counts, without the underlying absolute numbers that would let outsiders independently check the math. The table below lays out exactly what is on the record for each chip as of this reporting.
| Specification | Maia 200 | Maia 300 |
|---|---|---|
| Generation | Second-generation Azure accelerator | Third-generation Azure accelerator |
| Process node | TSMC 3nm | Not disclosed in confirmed reporting |
| Memory | 216GB HBM3e | Not disclosed in confirmed reporting |
| Memory bandwidth | 7TB/s | Not disclosed in confirmed reporting |
| On-chip SRAM | 272MB | Not disclosed in confirmed reporting |
| Transistor count | More than 140 billion | Not disclosed in confirmed reporting |
| FP4 compute | More than 10 petaflops | Not disclosed in confirmed reporting |
| FP8 compute | More than 5 petaflops | Not disclosed in confirmed reporting |
| Thermal design power | 750W SoC TDP | Not disclosed in confirmed reporting |
| Chips per rack | Baseline (half of Maia 300’s count) | 96, twice the Maia 200 rack count |
| Rack-level throughput vs. Maia 200 | Baseline | Up to 7x, per Microsoft |
| Tokens per megawatt vs. GPU systems | Not the stated comparison point | 40% more, per Microsoft |
| Target production timeline | Already supporting GPT-5.2, Foundry, and Copilot workloads | 2027 |
| Public pricing | Not published | Not published |
The Custom Silicon Race: Microsoft, Google, Amazon and OpenAI
Microsoft is not alone in this bet, and that is really the bigger story underneath the Maia 300 headline. The reporting around this announcement names Microsoft, Google, Amazon, and OpenAI as companies developing or accelerating their own custom-chip programs, a lineup that covers nearly every major buyer of Nvidia hardware at hyperscale.
Google has run its own Tensor Processing Unit program for years, and shattered.io recently detailed how Google’s Ironwood TPU undercuts Nvidia’s B200 on cost. Amazon has pushed its Trainium line for AI training and inference workloads inside AWS, a strategy that intersects with the company’s own chip leaseback arrangement with Nvidia covered here previously. OpenAI, for its part, has been tied to its own silicon effort as well, which shattered.io examined in a piece on OpenAI’s Jalapeño chip and its latency claims against Nvidia hardware.
Each of these programs is optimized for its own company’s workloads rather than built as a general-purpose product Nvidia and AMD would compete against on an open market. Microsoft’s Maia effort fits that same pattern: it is designed around Azure-controlled inference traffic, not sold as a chip any outside customer can buy off a shelf. That distinction is why chip-design specialists such as Marvell have built an entire business model around helping hyperscalers design this kind of custom silicon, a trend shattered.io covered in its look at Marvell’s custom-silicon push into the AI chip market.
| Company | Custom chip program | Primary stated purpose |
|---|---|---|
| Microsoft | Azure Maia (now at Maia 300) | AI inference for Microsoft products and Azure services |
| Tensor Processing Units | Training and inference across Google’s AI stack | |
| Amazon | Trainium | AI training and inference inside AWS |
| OpenAI | In-development custom accelerator | Reducing dependence on external GPU supply |
| Nvidia | Broad GPU accelerator platform (not a hyperscaler-specific chip) | General-purpose AI training and inference sold to all cloud providers |
| AMD | Instinct accelerator line (not a hyperscaler-specific chip) | General-purpose AI training and inference sold to all cloud providers |
From Maia 100 to Maia 300: A Short History of Microsoft’s Chip Bet
Microsoft’s custom silicon program did not start with Maia 300, and understanding the arc helps explain why the company is comfortable making bigger claims now than it did a few years ago. Microsoft first showed its original Maia accelerator back in 2023, positioning it as a long-term infrastructure play rather than a quick GPU substitute. Maia 200 followed as the generation that actually reached production, taking on real inference traffic for products Microsoft cannot afford to run inconsistently, including Copilot.
Maia 300 represents the point where Microsoft is willing to say, in public, that it wants this family of chips to become the primary inference system for its own products. That is a meaningfully stronger claim than “a chip we also use sometimes.” Coverage from The Verge framed the announcement around exactly that shift: a new chip explicitly aimed at making Microsoft less reliant on Nvidia’s GPUs for the workloads Maia is built to handle.
Microsoft is also not building Maia in isolation from everything else in its data centers. The company has described Maia as co-designed with its own networking, rack infrastructure, and software stack, treating the chip as one piece of a broader system rather than a drop-in GPU replacement. That system-level approach echoes how Microsoft has approached other custom hardware bets recently, including its work forming Xbox Labs to explore chip portability across platforms, a reminder that Microsoft’s hardware ambitions now extend well beyond Azure’s server racks.
Market Impact: Reading the Reaction From Wall Street and the Supply Chain
Announcements like this one tend to ripple through the AI hardware supply chain well beyond the company that made them. Rival cloud providers racing their own chip programs, from CoreWeave’s recent push with new server-grade CPUs built around Nvidia’s Vera platform (something shattered.io covered in detail in its piece on CoreWeave’s Vera CPU deployment for AI agents) to Intel’s own entry into the AI accelerator market with its Crescent Island GPU, all compete for the same pool of data-center power, floor space, and customer budget that Maia 300 is now chasing too.
For Nvidia and AMD specifically, the near-term financial exposure from Maia 300 looks limited. Microsoft’s own statements make clear that Maia 300 targets inference, not training, and that the company is not committing to drop GPU purchases. Training workloads, which still run disproportionately on Nvidia hardware, remain untouched by this announcement. The more meaningful signal for markets is directional: Microsoft, Google, Amazon, and OpenAI investing in custom chips simultaneously tells component suppliers, memory makers, and foundries that demand for hyperscaler-designed silicon is now a durable category, not a side experiment a single company might abandon.
TSMC, which fabricates Maia 200, sits in an interesting position here. Whether Microsoft buys more Nvidia GPUs or more of its own Maia chips, TSMC’s foundries are likely doing the manufacturing either way, which somewhat insulates the chipmaking supply chain even as the balance of power shifts between GPU vendors and their hyperscaler customers.
The Reported 1 Million Chip Number, and Why It’s Still Unconfirmed
One figure circulating widely in coverage of this announcement claims Microsoft intends to deploy more than 1 million Maia 300 chips. That specific number traces back to secondary reporting rather than Microsoft’s own public announcement text. South Korean outlet SBS carried the figure in its coverage, attributing large-scale deployment plans to Microsoft starting next year, but the underlying Microsoft materials reviewed for this story do not themselves spell out a precise chip count.
That gap matters for how readers should weigh the number. A million-chip deployment would represent an enormous manufacturing and power commitment, on the scale of the largest GPU buildouts anyone has announced. It is plausible given Microsoft’s stated ambition to reach multi-gigawatt scale by 2027, and the rack math (96 chips per rack, scaling to thousands of racks across new and existing data centers) is consistent with a seven-figure total chip count over time. But plausible is not the same as confirmed, and readers should treat the 1 million figure as a reported estimate rather than an official Microsoft disclosure until the company states it directly.
What Could Go Wrong Before 2027
A 2027 production target gives Microsoft more than a year of runway, and that runway carries real risk. Custom silicon programs have a track record of slipping schedules once a chip moves from announcement to volume manufacturing. Yield problems at advanced process nodes, packaging bottlenecks for high-bandwidth memory, and software compatibility issues across Microsoft’s own model stack can each push a 2027 target into 2028 without much warning.
There is also a simpler risk: demand for AI inference keeps climbing faster than any single chip program can absorb. Even if Maia 300 hits every target Microsoft described at OCP, Azure’s overall AI workload could grow enough that the company still needs to buy more Nvidia and AMD hardware alongside its own chips, not instead of them. Microsoft has effectively acknowledged this already by stating that building Maia 300 does not mean it will stop buying GPUs. The real test for Maia 300 is not whether it exists on schedule. It’s whether Microsoft’s own product teams trust it enough to route a majority of Copilot and Foundry traffic onto it once it ships.
Five Predictions for Custom AI Silicon Through 2027
- Microsoft will publish independent-style benchmarks for Maia 300 closer to its 2027 production date, once it has systems running real Copilot and Foundry traffic rather than conference-stage estimates.
- Nvidia’s quarterly earnings calls through 2027 will keep fielding questions about hyperscaler custom silicon, but the company’s training-workload revenue is unlikely to show material near-term damage from Maia 300 specifically.
- At least one of Google, Amazon, or OpenAI will announce its own next-generation custom chip before Microsoft actually ships Maia 300 at volume, keeping the “everyone builds their own chip” narrative in the news cycle through 2027.
- The still-unconfirmed 1 million chip figure will either get a direct Microsoft confirmation or quietly disappear from the company’s own messaging as the 2027 timeline approaches.
- Power availability, not chip design, will end up being the binding constraint on how fast Microsoft can actually reach multi-gigawatt Maia deployments, regardless of how efficient Maia 300 proves to be per chip.
Related
- Google’s Ironwood TPU Undercuts Nvidia B200 by 18%
- OpenAI’s Jalapeño Chip Claims 3.6x Lower Latency Than Nvidia
- Amazon’s $8B Nvidia Chip Leaseback Deal
- Marvell’s Custom Silicon Bet Targets $30B AI Market
- Intel Crescent Island GPU Ships at 1.3 PFLOPS, 480GB
Frequently Asked Questions
What is Microsoft Maia 300?
Maia 300 is Microsoft’s third-generation custom AI accelerator, announced on October 12, 2026. Microsoft says it is designed primarily to handle AI inference and is intended to become the primary inference system for Microsoft products and services, with production deployments targeted for 2027.
Does Maia 300 mean Microsoft is dropping Nvidia and AMD?
No. Microsoft has said its own silicon will mainly handle AI inference requests, and this does not confirm that Microsoft will stop using Nvidia or AMD processors. Training workloads in particular are expected to keep relying heavily on GPU hardware.
How much faster is Maia 300 than Maia 200?
Microsoft says rack-scale Maia 300 systems are expected to deliver up to seven times the token throughput of Maia 200 systems, helped by fitting 96 Maia 300 chips into a rack, twice the number of Maia 200 chips per rack.
What does “40% more tokens per megawatt” actually mean?
It is Microsoft’s claim that Maia 300 systems can process 40% more AI tokens for every megawatt of electricity consumed, compared with leading GPU-based systems. It is a power-efficiency claim rather than a raw speed claim, and it comes from Microsoft rather than an independent benchmark.
When will Maia 300 actually be deployed?
Microsoft has targeted production deployments beginning in 2027, with plans to expand Azure Maia to multi-gigawatt scale starting that same year.
Is it true Microsoft will deploy over 1 million Maia 300 chips?
That figure has appeared in secondary reporting, including South Korean outlet SBS, but it is not confirmed in Microsoft’s own public announcement materials. It should be treated as a reported estimate rather than an official company disclosure for now.
What is Maia 200 used for today?
Maia 200 is built on TSMC’s 3nm process with 216GB of HBM3e memory and is designed to support models including OpenAI’s GPT-5.2, as well as Microsoft Foundry and Microsoft 365 Copilot.
Which other companies are building their own AI chips?
Microsoft, Google, Amazon, and OpenAI are all identified in current reporting as companies developing or accelerating custom-chip programs, alongside Microsoft’s own Maia family.